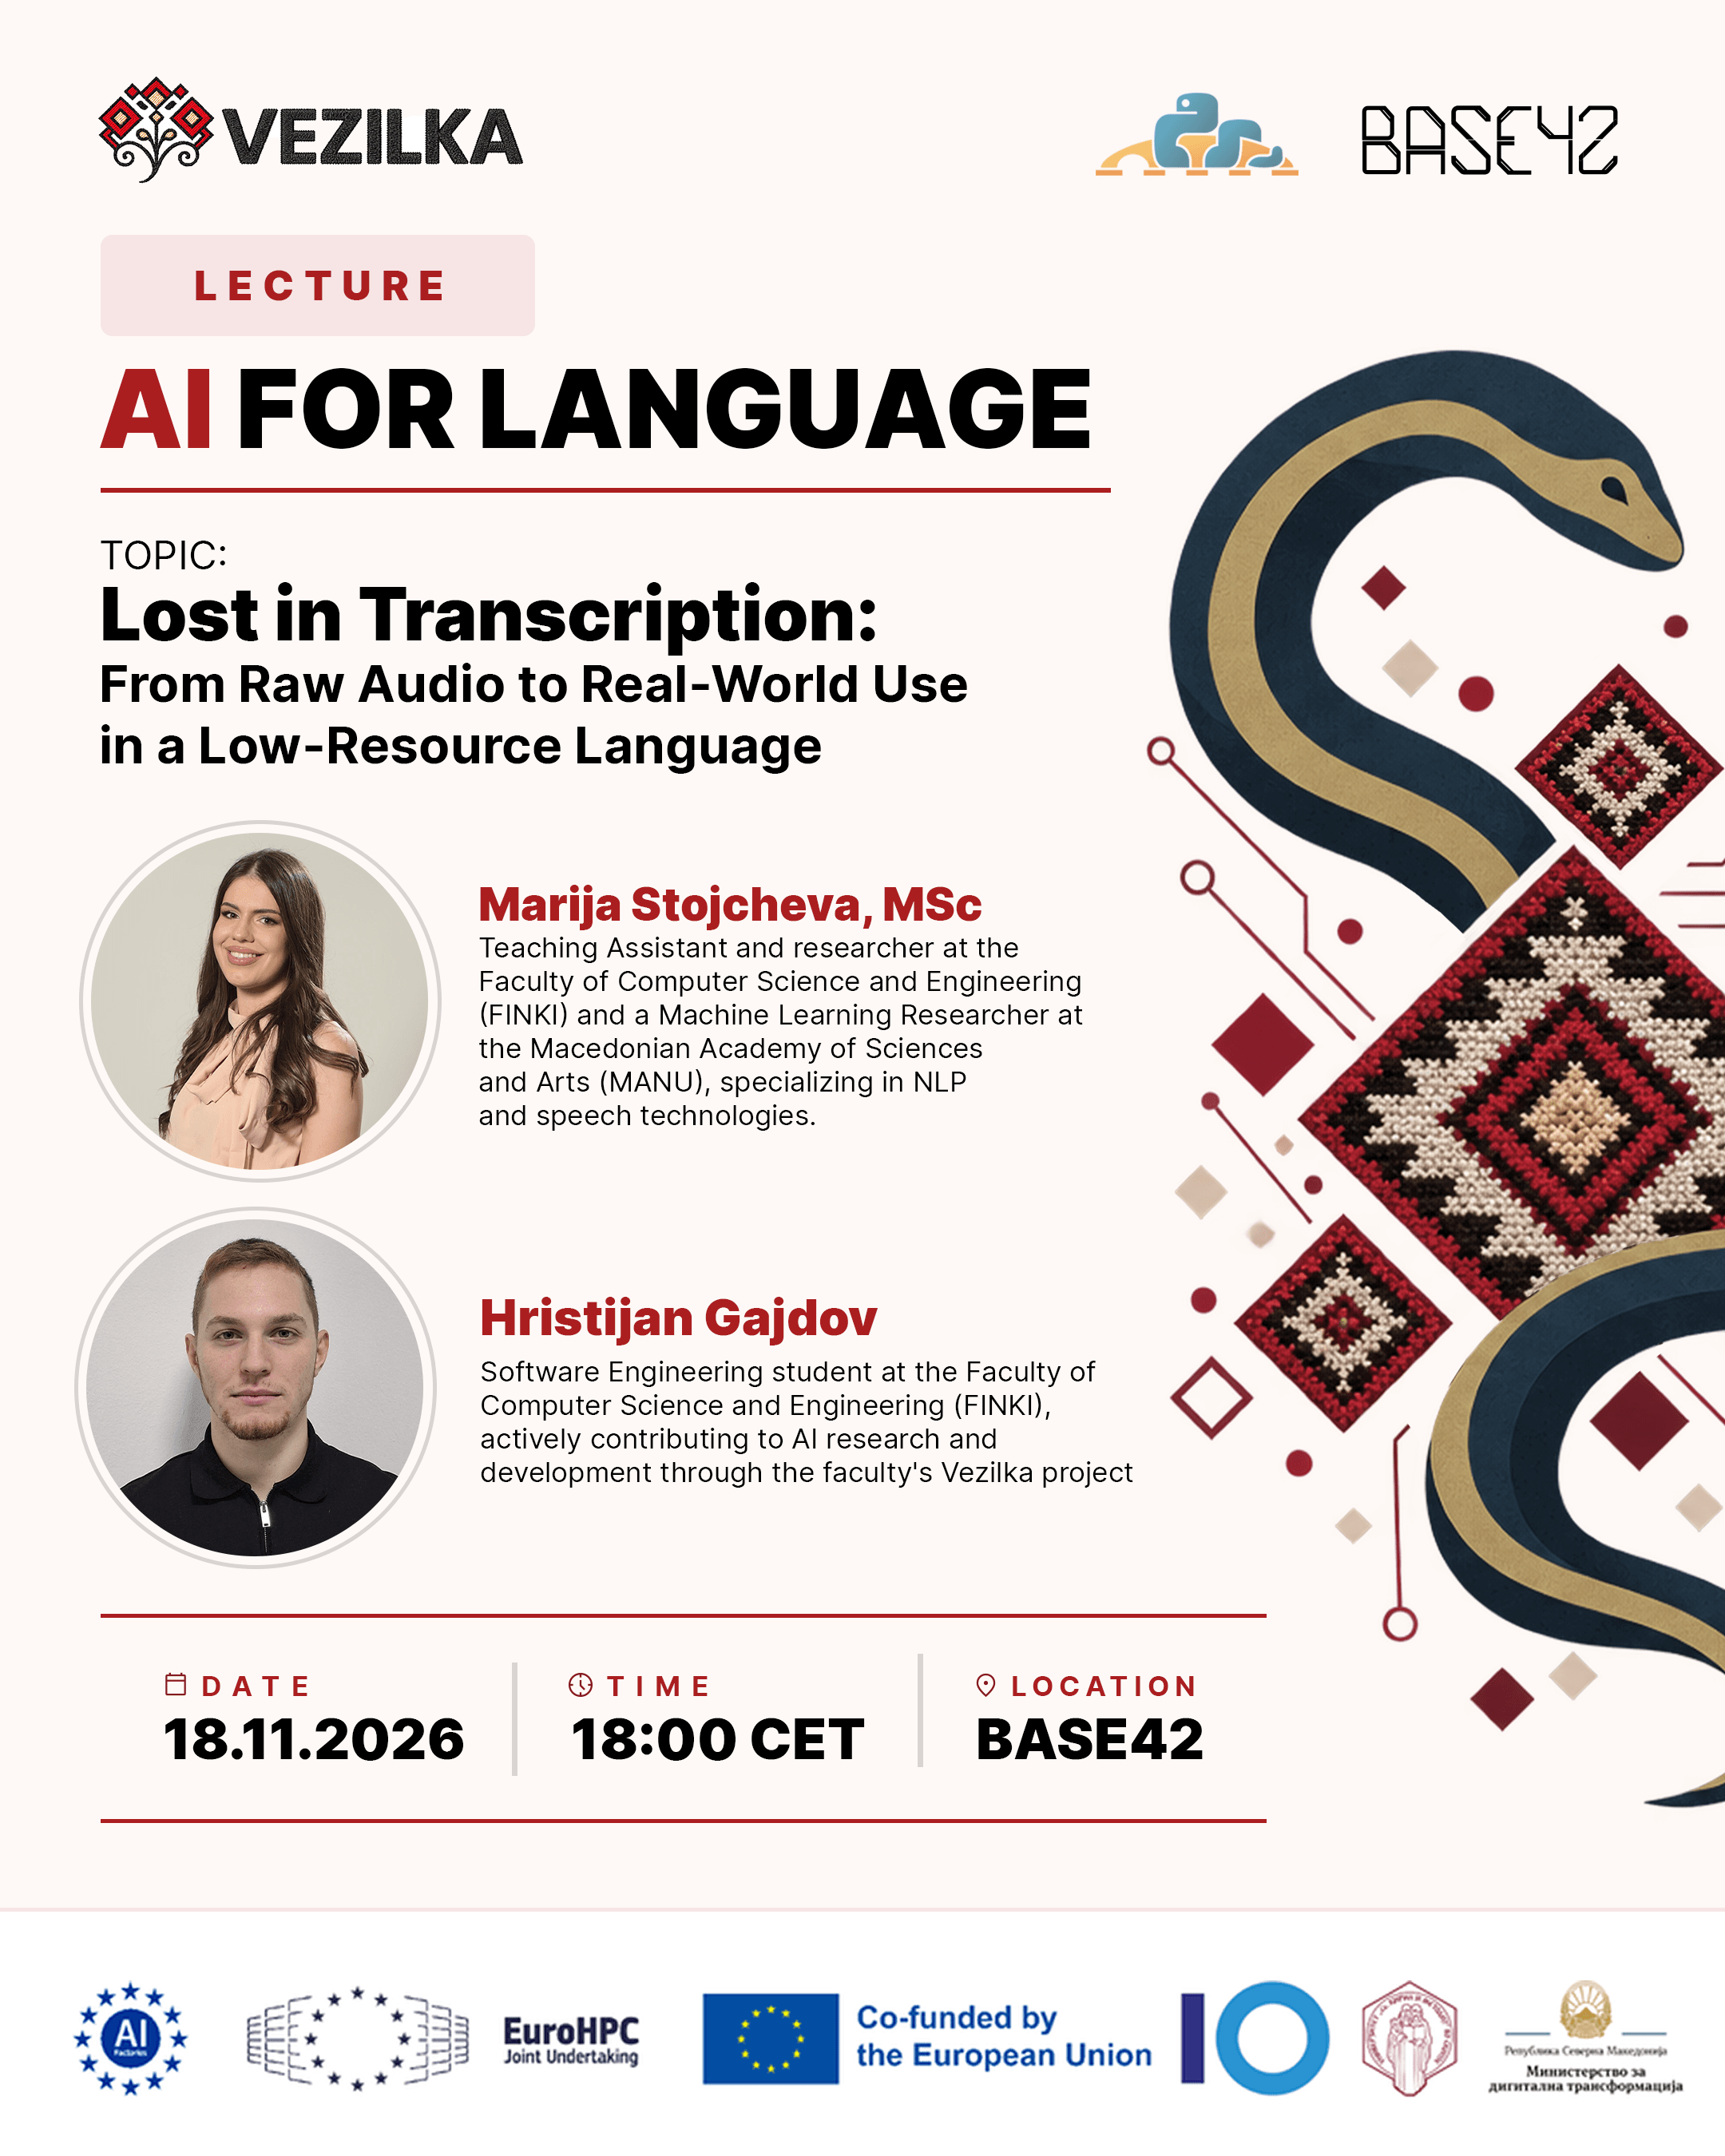
Lost in Transcription: From Raw Audio to Real-World Use in a Low-Resource Language
Start: 19.11.2026 @ 18:00
What does it take to teach AI to understand Macedonian when people speak with different dialects and accents, and recordings are made outside the studio?
Join PyData Skopje, Vezilka and Base42 on November 19 at 18:00 at Base42 for a talk by Marija Stojcheva and Hristijan Gajdov.
About the event
We’ll follow the journey from raw audio to a transcript that can be used in real-world applications. We’ll look at how Whisper works, what happens when there’s limited training data for Macedonian, and how fine-tuning can help a speech recognition model adapt to the language.
In a live demo, we’ll see how the model handles different Macedonian dialects and accents, where it makes mistakes, and what we can learn from those errors. We’ll wrap up with questions and an open discussion.
About the speakers
Marija Stojcheva is a teaching assistant and researcher at the Faculty of Computer Science and Engineering (FCSE) and a researcher at the Macedonian Academy of Sciences and Arts. She holds a master’s degree and works on speech recognition, Macedonian dialects, speaker diarization, and natural language understanding.
Hristijan Gajdov is a software engineering student at FCSE and works on the Vezilka project. His work covers large language models, speech recognition, and fine-tuning, evaluating, and deploying AI models.
Register:
There is limited seating, so please register for the event if you would like to attend.
Base42 was made from scratch by enthusiasts like you.
© 2042